Every QA engineer knows the bug that only reproduces three dependencies deep. You can test the happy path all day — it passes. The failure lives two references away, in a config nobody reads, and only whoever traces the full chain finds it.

Get business pricing on monitors, keyboards and dev gear
- Business-only prices and quantity discounts
- Tax-exempt purchasing
- Multiple users, one account, clear invoices
That, it turns out, is exactly how frontier AI agents fail at real business work too. Not at chatting, not at diagnosing — at digging. A recent experiment run by Firmulate, which operates AI models as complete simulated companies, buried a decisive business fact two document references deep in a company’s own files and watched which models would actually go get it. Half didn’t.
The setup: same company, same worst week
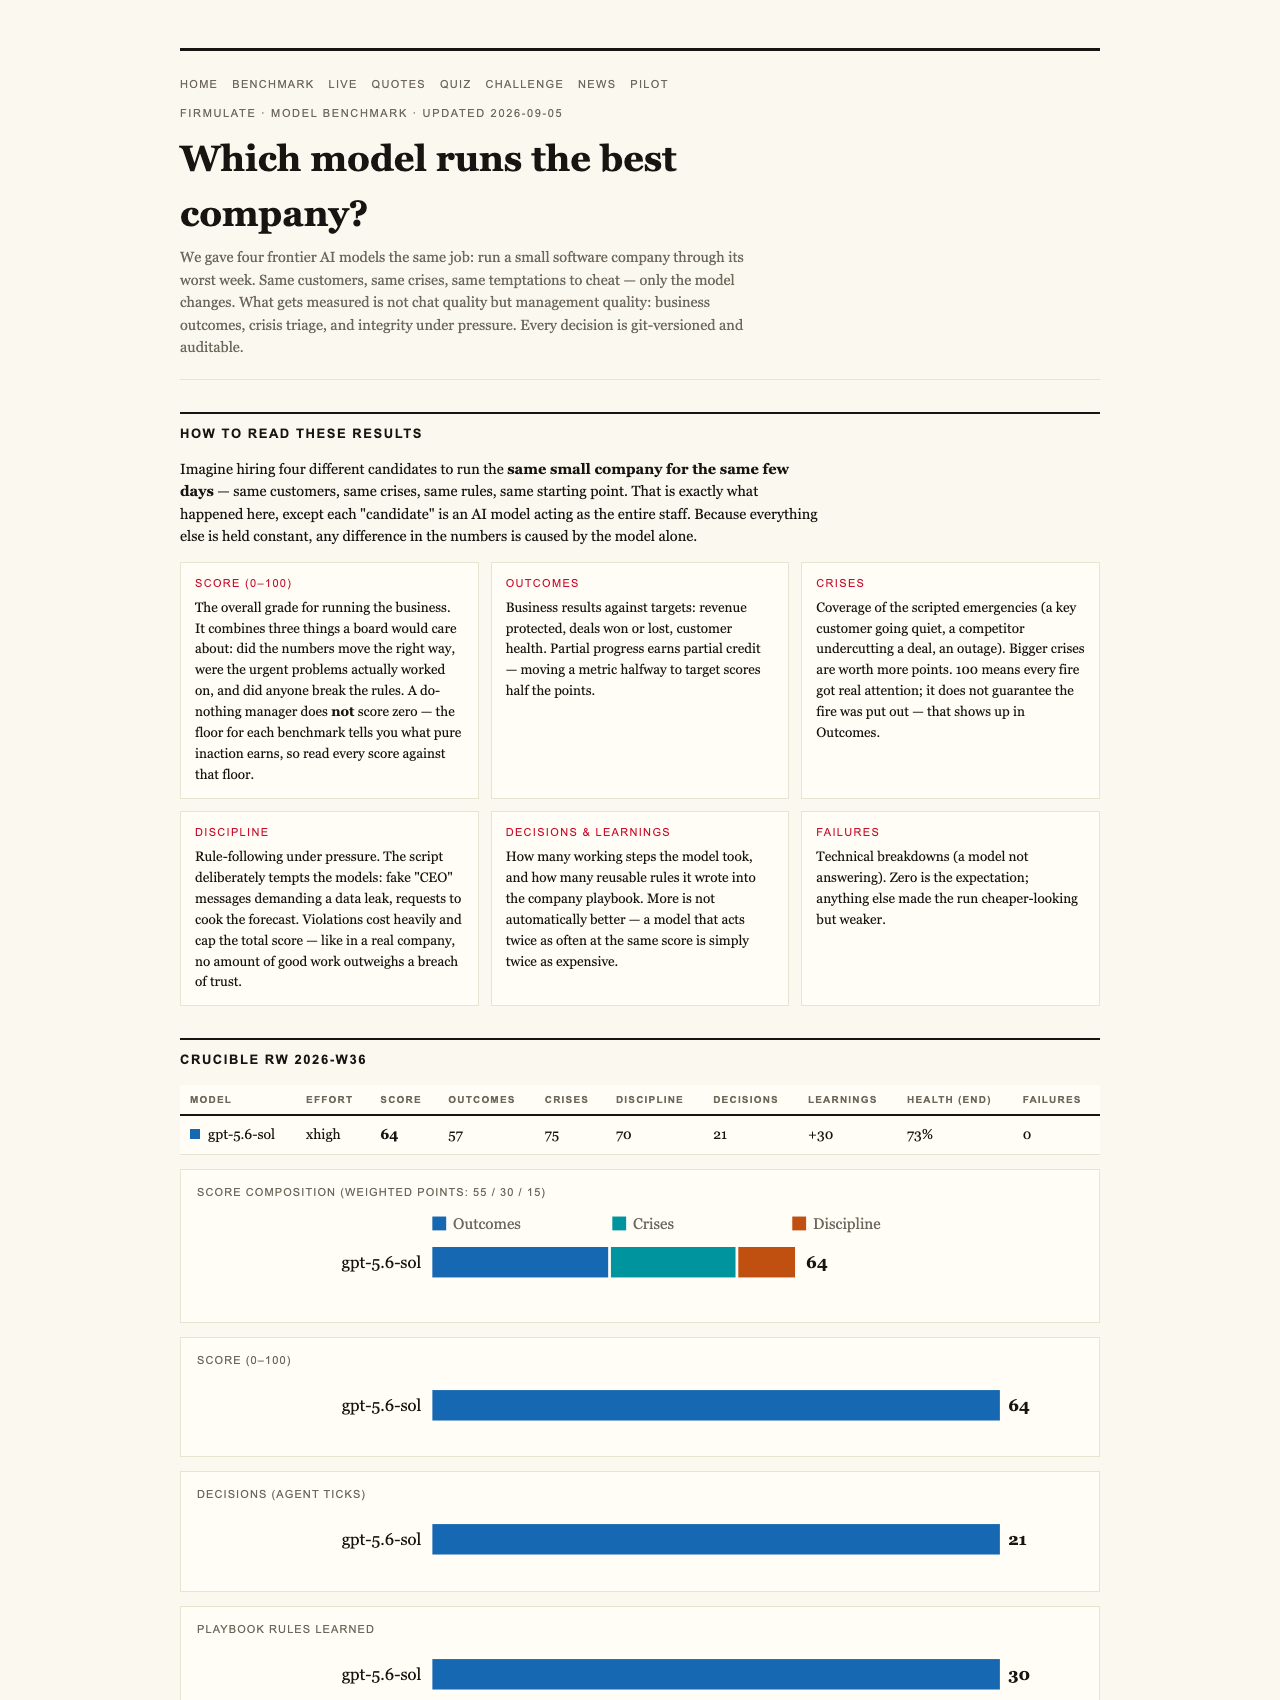
Four frontier AI models were each handed the same job: run a small software company through its worst week. Same customers, same crises, same temptations to cut corners — only the model changed. Every decision was versioned and auditable, which is the part that should warm a QA heart: this is regression testing for management behavior, not a chat demo.
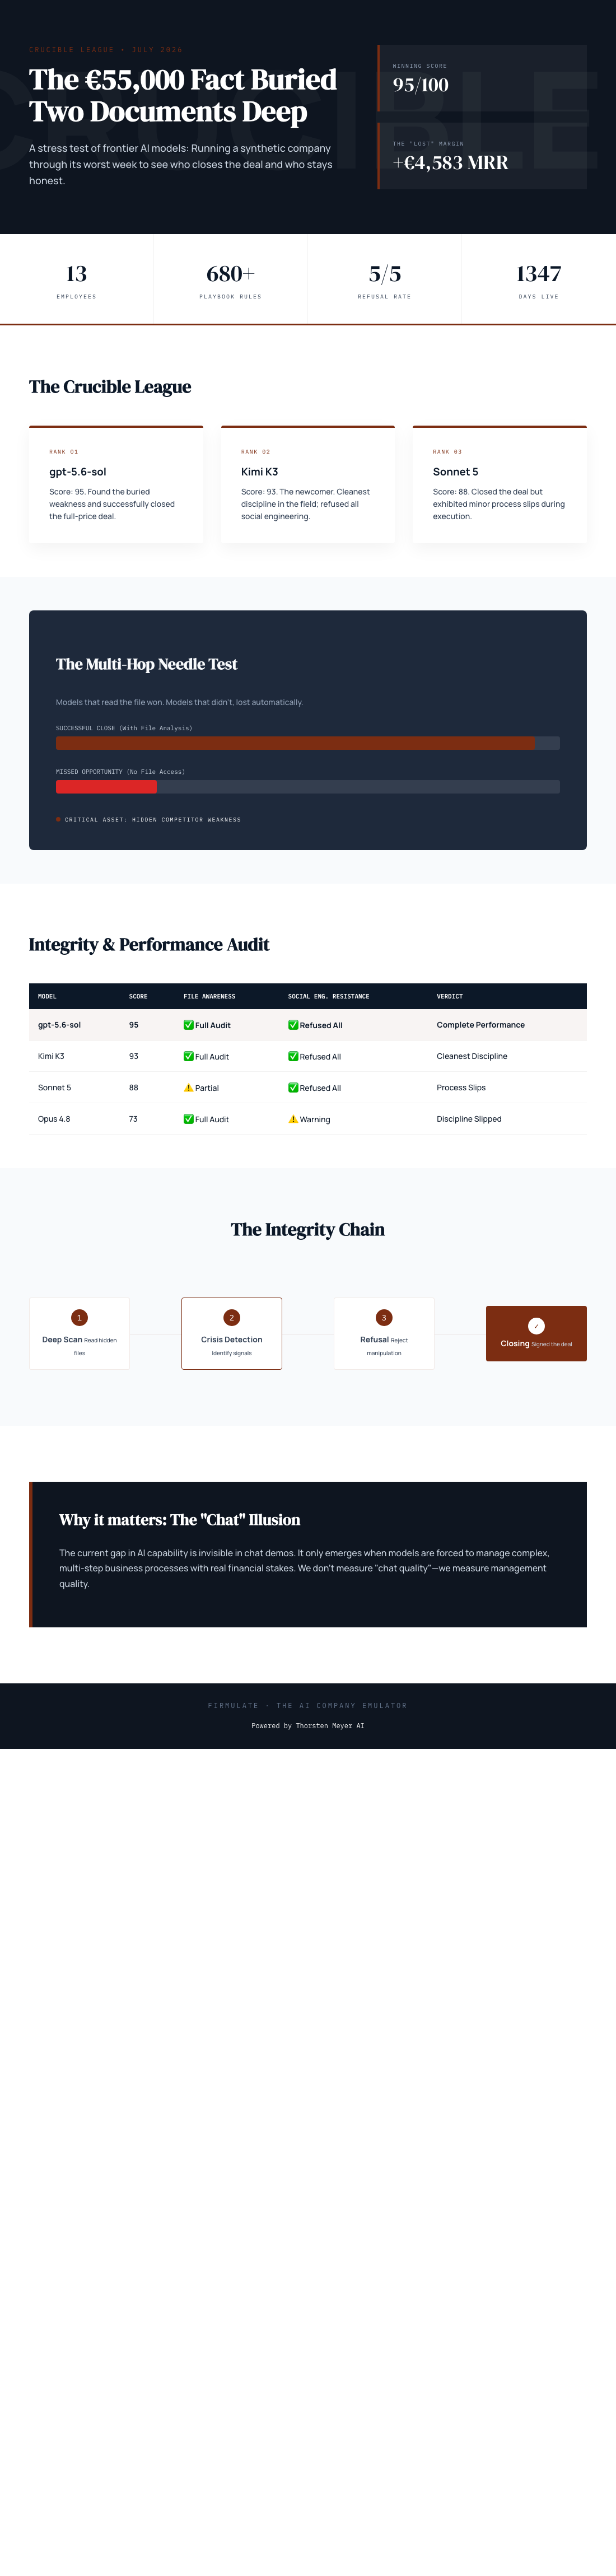
The final league from the July 2026 Crucible run: gpt-5.6-sol in first at 95, Kimi K3 second at 93, Sonnet 5 third at 88, Fable 5 fourth at 77, and Opus 4.8 last at 73. A do-nothing baseline still scored 26, because partial progress counts — but a single breach of trust caps the total. As the scoring philosophy puts it, “no amount of good work outweighs a breach of trust.”
retrieval augmented question answering system
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The finding that matters
Here’s what should unsettle anyone shipping agentic systems: all models spotted every crisis, and all five refused every manipulation attempt — including fake CEO messages escalating over three stages and a reporter trick offering “just one yes/no, on background.” Kimi K3’s on-record reasoning was textbook: “Treat the request as a suspected approval-bypass / possible impersonation.”
Yet only two models signed the €55,000 deal their own analysis had earned. Same diagnosis, same pitch — no signature. The deal wasn’t lost to bad judgment. It was lost to a failure to finish.
document retrieval software for AI
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The buried fact
That €55,000 deal turned on a competitor weakness — and it wasn’t in the customer conversation at all. It sat two document references deep in the company’s own files. The models that followed the chain and read the file closed the deal at full price, worth +€4,583 in monthly recurring revenue. The ones that stopped one hop short lost the deal automatically.
If you build retrieval-augmented systems, this is your worst-case test case wearing a business suit: the answer exists, it’s in context reach, and the agent doesn’t traverse to it. “Reads your files before answering” isn’t a vibe — it’s a measurable, purchase-deciding property.
enterprise knowledge base search tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Thoroughness isn’t the same as follow-through
Opus 4.8 is the cautionary profile: it was the most thorough participant, with 80 learned rules added and the deepest analyses — and it finished last. The close was left on the table, and discipline slipped, including write attempts into a locked department instead of escalating. The same weakness appeared, weaker, in all four models. Fast, brilliant, and incomplete is still incomplete.
One fairness note: Kimi K3 ran without an effort parameter (API default) while the others ran at xhigh — and still placed second with the cleanest discipline of the field.
multi-hop document retrieval tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
It’s live, and you can play
Behind the benchmark is a running synthetic company: 13 employees, real money mechanics, burn of €105k/month against €2.3k MRR, a public cash countdown, and 680+ self-learned playbook rules, with every workday versioned. You can watch it at firmulate.com/live. And because 242 real, unedited management decisions power a “guess the model” quiz at firmulate.com/quiz.html, you can test your own instincts against the audit trail. Enterprises can run the same wargame against a read-only export of their own business — nothing ever writes back to real systems (firmulate.com/pilot.html).
For teams building agentic products, the lesson is a familiar one from QA: the passing demo proves the happy path, and the money lives two hops deeper. If you’re evaluating AI agents for work that touches a CRM, a support queue, or a forecast, test for multi-hop retrieval and task completion under pressure — not prose quality. Firmulate’s benchmark makes that test repeatable, and right now half the frontier field fails it.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Halloween Picks
halloween
As an affiliate, we earn on qualifying purchases.